TECHNOLOGY · CLOUD INFRASTRUCTURE · WEB ARCHITECTURE
The Microsoft Global Outage of November 2026: A Wake-Up Call About Cloud Dependency
Imagine opening your laptop on a normal working day, expecting to check your emails, join a Teams meeting, review your project documents, and continue working with your usual tools.
You open Outlook. Nothing.
You try Microsoft Teams. Still having problems.
You switch to Microsoft 365, SharePoint, or Copilot. Those services are experiencing disruptions too.
Now imagine millions of people experiencing the same thing across different countries, businesses, and industries.
That was the reality of the November 12–14, 2026 Microsoft service disruption, which affected users across the world and exposed just how much modern businesses depend on a relatively small number of technology providers.
I'm Biswajit Mazumdar, a web developer, software architect, and technical technology professional. Working across custom web applications, PHP development, technical SEO, SaaS platforms, and infrastructure has made me particularly interested in one question:
What happens to your business when the technology you depend on suddenly becomes unavailable?
This incident is worth discussing, not just as another technology outage, but as a lesson in how we design, manage, and depend on digital infrastructure.
When Essential Microsoft Services Suddenly Became Unavailable
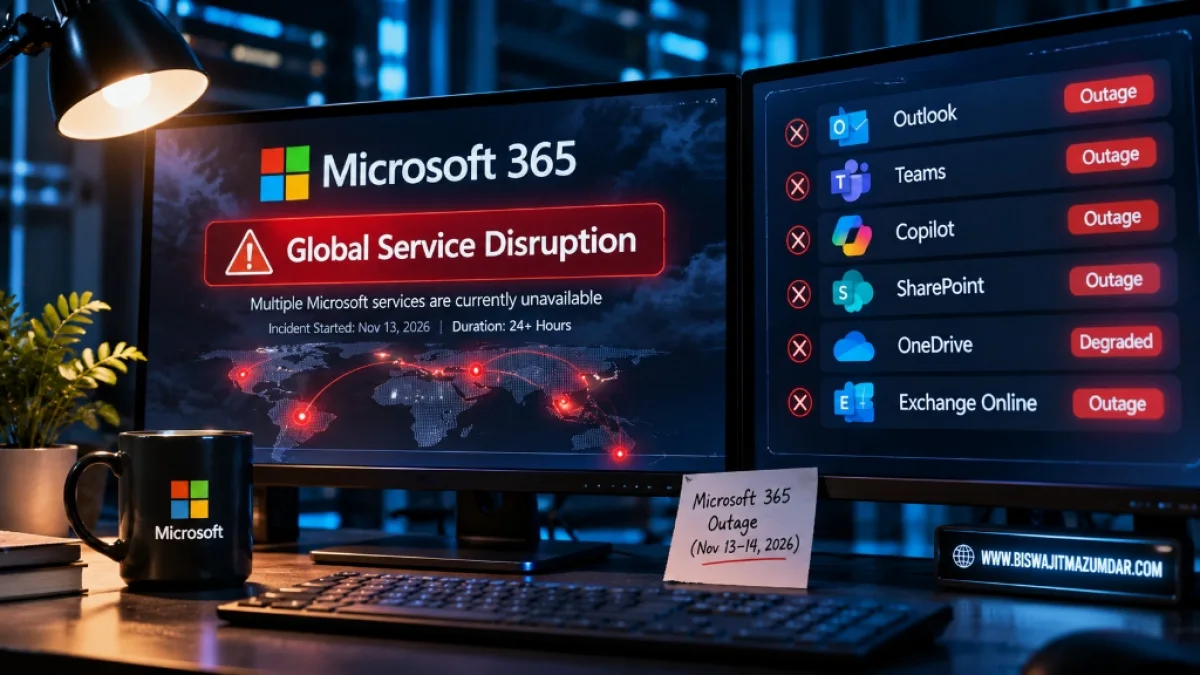
The disruption began on Thursday, November 12, in the United States and continued into November 13 across other regions, with recovery activities extending into November 14.
Several important Microsoft services experienced connectivity problems, including:
- Microsoft Outlook and Exchange Online.
- Microsoft Teams.
- Microsoft 365 services.
- Microsoft SharePoint Online.
- Microsoft Copilot for Microsoft 365.
- Other connected Microsoft business services.
The Associated Press reported nearly 130,000 Outlook problem reports on Downdetector shortly after 1 PM Eastern Time on November 12. Users reported problems accessing inboxes, sending messages, and receiving emails.
The disruption was not limited to ordinary office users. Government IT infrastructure in Japan was also affected, and organizations across different countries reported difficulties accessing their Microsoft services.
In India, IndiGo and Akasa Air reported disruption or delays affecting their email support channels. Their statements clarified that flight operations remained unaffected.
You can read the reporting from the Associated Press and The New Indian Express.
What makes this incident particularly interesting is the number of services that were affected through their shared infrastructure and dependencies.
A business might use Outlook for communication, Teams for collaboration, SharePoint for documents, and Copilot for assistance. When several of these services become unavailable together, the disruption reaches much further than a single application.
The problem is no longer simply that an application is down. It is that the business processes built around that application may stop working.
What Actually Happened Inside Microsoft's Infrastructure?
This is the part I find particularly interesting from a technical perspective.
During the initial investigation, Microsoft reported elevated infrastructure load across multiple regions. It also identified a large number of servers becoming unexpectedly unavailable, shifting additional workload onto the remaining infrastructure.
One of the early findings involved automated server health checks.
These checks are designed to help infrastructure systems determine whether individual servers are healthy enough to receive traffic. When a server fails its health check, it can be removed from the available pool to protect the wider service.
According to Microsoft's incident updates, affected servers were failing these automated checks. Microsoft investigated a component responsible for processing the checks and tested an alternative health-check method to bring affected infrastructure back into service.
The situation became more complicated because the remaining servers were handling additional workloads as capacity decreased.
That is an important infrastructure problem: removing unhealthy servers is normally a protective mechanism. But when too many otherwise necessary servers become unavailable together, the remaining capacity can become overwhelmed.
Microsoft's November 14 update provided further information. The company attributed the incident to an issue during an earlier network-capacity upgrade that surfaced following a recent network change. It said the underlying issue had been addressed and that services were being restored gradually.
Microsoft also stated that this was not a cyberattack or an issue caused by AI agents. A full post-incident report was still expected.
The distinction matters. The initial health-check observations help explain how the infrastructure behaved during the incident, while the later network-capacity explanation describes the reported underlying cause. We should not treat every early theory about the failure as the final root-cause analysis.
Sources: ABC News — Microsoft outage investigation and the Microsoft service-status updates reproduced by THERS.
The Real Problem: We've Built Businesses Around Centralized Technology
Now let's move away from Microsoft's individual infrastructure problems.
I think the bigger issue is how businesses have become dependent on centralized digital ecosystems.
Consider a typical modern business:
- Email runs through Microsoft 365.
- Documents are stored in SharePoint or OneDrive.
- Internal communication runs through Teams.
- Project management depends on a cloud-based SaaS platform.
- Customer information sits inside a hosted CRM.
- Business automation depends on third-party APIs.
- AI-powered workflows rely on external model providers.
Individually, these services can be excellent. They reduce infrastructure-management work, provide convenient collaboration tools, and allow businesses to operate without maintaining every server themselves.
I use cloud platforms and external services too. There is absolutely nothing wrong with choosing managed infrastructure when it makes operational and financial sense.
The problem begins when a business has no practical alternative.
Imagine that your entire customer communication process depends on one email provider. Your employees use single sign-on through that provider. Important documents are available only through its cloud storage. Your automated workflows also depend on its APIs.
Now that provider experiences a widespread outage.
You may still have an internet connection, working computers, and functioning office infrastructure. But your normal business workflow is suddenly blocked.
That is what I mean by dependency risk.
The cloud may remove the responsibility of operating your own infrastructure, but it doesn't remove the responsibility of planning for service failure.
Vendor Lock-In: Convenience Today, Dependency Tomorrow
Vendor lock-in is one of those subjects that often gets ignored when everything is working perfectly.
A particular platform makes it easy to get started. You connect your business, upload information, configure integrations, and gradually build your entire workflow around it.
After a few years, leaving that platform becomes considerably more complicated.
Your data may be exportable, but the application logic, integrations, user permissions, automation rules, and business processes may not transfer easily.
You might technically own your business data while still depending heavily on the provider's application to access and use it.
That is an important distinction.
When I evaluate technology for a project, I prefer asking a few questions before choosing a platform:
- Can the business export its important data?
- Can the application operate independently of a specific third-party service?
- What happens when an external API becomes unavailable?
- Can another provider replace the dependency without rewriting the entire application?
- Are backups accessible outside the primary platform?
- Does the business have an alternative communication channel?
I don't believe every dependency needs to be eliminated. That would be unrealistic.
But dependencies should be understood, documented, and managed instead of being introduced without considering their long-term consequences.
Microsoft's 2026 Outage and CrowdStrike's 2024 Incident: Different Failures, One Important Lesson
Many people naturally remember the CrowdStrike incident of July 19, 2024 when discussing major technology outages.
That incident involved a faulty content-configuration update for CrowdStrike's Falcon sensor that caused affected Windows systems to crash. Microsoft estimated that approximately 8.5 million Windows devices were affected.
You can read the original CrowdStrike Root Cause Analysis summary.
There is an important technical difference between the two events.
The CrowdStrike incident involved an endpoint security-software configuration update that caused Windows system crashes.
The November 2026 Microsoft incident involved Microsoft 365 infrastructure, network capacity, server availability, and related health-check problems.
They were not the same technical failure.
But both demonstrate how problems within widely deployed technology components can have consequences far beyond the original point of failure.
Microsoft itself discussed the wider importance of safe software deployment and disaster recovery after the CrowdStrike incident in its official response.
For me, the recurring lesson is straightforward: systems need more than a successful deployment process. They need a recovery plan when something goes wrong.
What I Would Do Differently as a Web Architect
Now comes the practical part.
If I were designing a business application, SaaS platform, or technical infrastructure today, I would spend more time identifying critical dependencies and planning how the system behaves when those dependencies fail.
Here are the principles I would prioritize.
1. Avoid making one external provider responsible for everything
Use third-party platforms where they provide genuine value, but avoid unnecessary concentration of critical business functions.
For example, the email provider, application hosting, data backup destination, and domain management shouldn't all become inaccessible through one avoidable failure.
This doesn't mean that every business needs multiple providers for every service. Redundancy introduces cost and operational complexity. The important thing is to identify which dependencies are critical enough to justify an alternative.
2. Keep important business data portable
I prefer systems where important business data can be exported in usable, documented formats.
Customer information, business records, application data, and configuration should not exist only inside an interface that the business cannot access independently.
Regular backups should be stored separately from the primary production environment, and restoration should be tested rather than simply assumed to work.
3. Build applications with independent components
A well-structured application should separate its core business logic from the external services it uses.
For example, if an application sends notifications through a particular email provider, that notification component should ideally be replaceable without rewriting the entire application.
The same principle applies to payment providers, storage systems, external APIs, authentication services, and other dependencies.
This is where modular software architecture becomes particularly useful.
4. Design for graceful degradation
Not every external service needs to be available for every part of an application to remain useful.
Suppose a restaurant's website uses an external reservation platform. If that provider becomes unavailable, the restaurant's homepage, menu, address, and opening hours should not necessarily disappear with it.
A sensible implementation can keep essential information accessible while clearly communicating which additional service is temporarily unavailable.
The same principle applies to CRM integrations, online payment services, and business automation workflows.
5. Build a realistic disaster-recovery plan
Every business should understand how it would continue operating during a technology disruption.
At minimum, I would want:
- Regular, independently stored backups.
- Documented restoration procedures.
- Alternative communication channels.
- Access to important business information outside the primary SaaS application.
- Monitoring and service-status notifications.
- Clear responsibilities for handling an outage.
- A tested process for switching to an alternative service when necessary.
A disaster-recovery document that nobody has ever tested is not much of a recovery strategy.
Why I Value Independent and Self-Managed Architecture
This is one reason I enjoy working with custom web applications and modular PHP architectures.
For many business projects, I prefer having direct control over the application's core logic, data structures, and deployment arrangements.
A custom PHP application can be designed without depending on a large collection of unrelated plugins or an entire website-builder ecosystem.
Using PHP, MySQL, Vanilla JavaScript, and a carefully organized application structure, it is possible to build systems where the business logic remains understandable and the components have clearly defined responsibilities.
That doesn't mean PHP automatically makes a website more secure, faster, or more resilient. Those qualities come from architecture, implementation, testing, infrastructure, and maintenance.
There is another important point: hosting a custom application on a single shared server still creates a dependency on that hosting provider. If its infrastructure fails, the application may become unavailable too.
So I wouldn't describe a custom PHP application as immune to cloud outages.
The real advantage is control and portability. Depending on the project, the application can be moved to another suitable hosting environment, its database can be backed up independently, and its business logic can remain separate from external integrations.
For systems where availability is critical, I would also consider redundant infrastructure, tested failover procedures, independent backups, and alternative service providers.
The objective is not to reject the cloud. It is to avoid becoming helpless when a particular part of it fails.
Even Small Businesses Need Business Continuity Planning
You might think disaster recovery and infrastructure redundancy are relevant only to large enterprises.
I disagree.
A small business can experience serious disruption if it cannot access email, customer information, invoices, appointment records, or its primary business application.
Consider a restaurant:
- The online reservation provider becomes unavailable.
- The restaurant cannot access an important supplier email.
- Its online ordering integration stops receiving orders.
- Its website depends on a third-party menu service that is experiencing an outage.
The restaurant might still be able to serve customers physically, but the disruption can affect communication, coordination, and daily operations.
A practical alternative doesn't have to be expensive.
It could be as simple as maintaining an accessible copy of the current menu, keeping important supplier contact details separately, providing a direct phone number, and ensuring that staff know what to do when the ordering system stops working.
For a larger operation, the requirements may be considerably more involved.
The important thing is to identify the systems that your business cannot afford to lose access to and prepare accordingly.
My Final Thoughts: Don't Confuse Convenience With Resilience
I use modern cloud services. I build applications that integrate with external APIs. I work with AI tools, hosted infrastructure, payment providers, and other third-party platforms.
I have no intention of suggesting that businesses should abandon these technologies.
They are useful, and in many situations they are the most practical choice.
But the November 2026 Microsoft outage is a reminder that even the largest technology providers can experience failures that affect services across multiple countries and industries.
No provider can honestly promise that its systems will never experience an outage.
As developers, architects, and business owners, we have to think beyond the convenience of the tools we use every day.
We need to understand our dependencies, protect our data, separate critical components, and make sure that one unavailable service doesn't bring the entire business to a standstill.
Good architecture isn't just about building something that works when everything is available. It's about deciding what should happen when something inevitably fails.
That's the kind of thinking I want to bring to every website, application, and digital product I work on.
Need a More Independent and Reliable Web Architecture?
Whether you're planning a custom business website, a PHP-based web application, a SaaS product, or a more integrated digital system, I believe the architecture should be designed around your actual business requirements—not unnecessary dependencies.
I'm Biswajit Mazumdar, and I work on custom web development, technical architecture, performance optimization, SEO, and digital product development.
If you're considering a new project or want to evaluate the technical foundation of an existing system, visit my professional portfolio to learn more about my work and services.
Explore Biswajit Mazumdar's Web Development & Technical Services →Sources & Further Reading
- Associated Press — Microsoft Outlook, Teams and Copilot outage
- ABC News — Microsoft outage investigation and recovery updates
- Microsoft 365 incident updates — November 2026
- The New Indian Express — Microsoft outage and Indian airline email disruptions
- CrowdStrike — Executive Summary of Root Cause Analysis, July 2024